
Probabilistic AI Regression Testing Needs to Know Which Differences Matter
Probabilistic AI regression testing distinguishes legitimate output variation from behaviour that should block a release. See how exact checks, criteria-based evaluation, repeated sampling and critical failure boundaries can identify meaningful regressions without treating every textual difference as a defect.

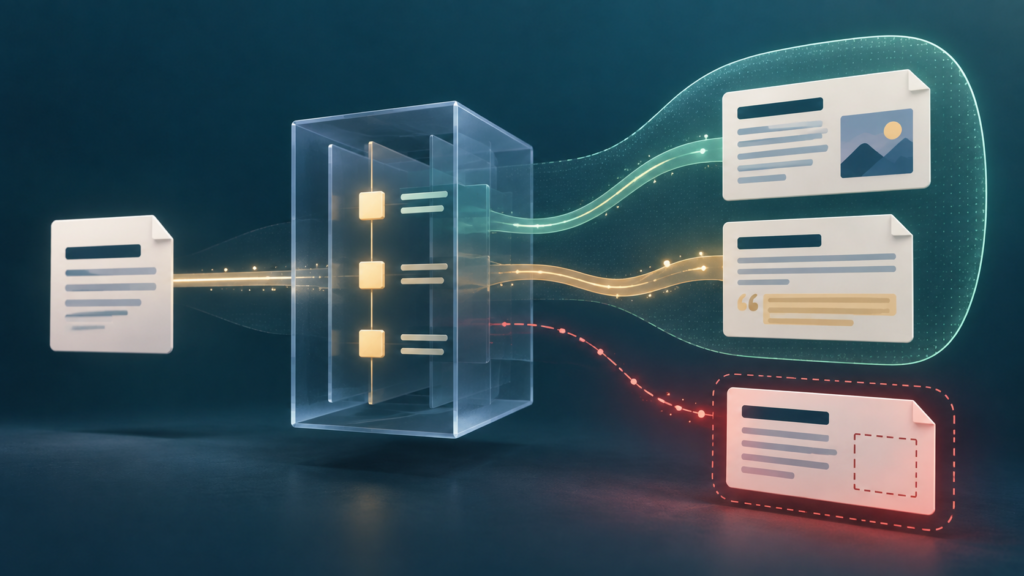
The same AI input can produce several acceptable outputs. Probabilistic AI regression testing therefore has to separate harmless variation from changes that alter required facts, task behaviour, safety constraints or the business outcome a system is expected to preserve.
A candidate model is run against a fixed regression set. One response changes only the order of two sentences, while another reaches the same answer through a different explanation. A third drops a fact the application is required to include.
An exact-output comparison can mark all three as failures. An average quality score can create the opposite problem: the third case may disappear inside an otherwise improving test run.
Before the team can decide whether the release regressed, the test suite has to know which differences actually matter.
That is a different problem from ordinary software regression testing. Generative systems can vary even when the input and application configuration remain unchanged. OpenAI’s evaluation best-practices guidance explicitly treats this variability as a reason traditional software-testing methods are insufficient on their own and recommends comparison, classification and criteria-based scoring for many evaluation tasks.
The difficulty is not simply that outputs are non-deterministic. It is that output difference and behavioural regression are no longer the same event.
What probabilistic AI regression testing should actually compare
Traditional regression testing has a useful property: a known input can often be associated with one expected output.
A calculation should return the same value. An API should respect the same contract, and a transformation should produce the expected record.
Free-form model behaviour is different.
Two summaries can use different sentences and preserve every decision-relevant fact. Two explanations can take different routes to the same conclusion. A classification response can express its reasoning differently while still returning the correct permitted category.
A regression suite built around one “golden” string can therefore become very good at detecting textual change and surprisingly poor at detecting degraded behaviour.
For probabilistic systems, the acceptance target often needs several layers.
The response may have to contain specific facts, remain grounded in supplied evidence and stay within an allowed action or recommendation boundary. A structured field may need to contain one of a fixed set of values. Certain failure modes may be unacceptable regardless of how strong the rest of the response is.
Other parts of the output may legitimately vary.
The regression test becomes more useful when those conditions are represented explicitly instead of being compressed into one expected answer.
This is also why pairwise evaluation can be valuable. Rather than asking whether a candidate output reproduces a stored response, a test can ask whether the candidate is better, worse or materially equivalent to the production baseline against defined criteria.
OpenAI specifically recommends pairwise comparison, classification and scoring approaches where they fit the task because models tend to evaluate constrained choices more reliably than open-ended generation.
The regression signal then comes from a deterioration in behaviour, not merely the existence of a diff.
Some AI behaviour still deserves exact tests
Accepting output variability does not mean every part of an AI application should receive probabilistic acceptance criteria.
A required JSON field either exists or it does not. A tool call can be restricted to an approved operation. A workflow can require a valid identifier before an external action proceeds, while a policy-controlled response may be prohibited from disclosing a particular class of information.
A classification system may also have an enumerated set of allowed labels.
These are useful deterministic surfaces inside a probabilistic application.
Problems arise when teams use the same testing logic for both kinds of behaviour.
If every generated sentence is treated like an API contract, harmless variation creates noisy failures. If every system property is treated as a fuzzy quality judgment, real contract violations become easier to excuse.
A mature regression set can therefore contain exact checks and probabilistic evaluations side by side.
The boundary depends on what the application is allowed to vary. That boundary is more valuable than trying to make the entire system behave as though variation did not exist.
One passing execution is weak evidence for a variable behaviour
There is another complication. A candidate release can pass a scenario once and still have become less reliable.
Suppose the production version almost always includes a required limitation in a generated recommendation. A candidate version sometimes omits it.
Running each test case once may produce a pass for both versions. Run the same important cases repeatedly, and the difference can begin to appear.
Microsoft’s Copilot Studio evaluation guidance for its production-ready preview agent-evaluation experience addresses this directly. It recommends repeated evaluation runs because language-model agents and model-based graders produce variable results; another Microsoft evaluation guide advises running each test set multiple times and looking at average success rates rather than interpreting one run as definitive.
That changes the unit of regression analysis.
For some behaviours, the relevant result is not simply pass or fail for this output. It is how often a failure appears across repeated executions, whether that frequency changed relative to the existing release, and whether the failures cluster around specific classes of task.
This does not require every test to become a statistical experiment. Exact contract checks remain exact.
Repeated sampling becomes valuable where the behaviour being tested can legitimately vary and where intermittent failure would matter in production.
Noisy regression tests eventually become an operating problem
Poorly designed probabilistic tests create more than inaccurate dashboards. They consume review capacity.
When a model upgrade produces hundreds of “failures” caused by wording changes, engineers and subject-matter experts have to adjudicate them. If most turn out to be harmless, the test suite starts training the team to distrust its own alarms.
The release gate weakens long before anyone formally removes it.
Teams begin approving known false positives in bulk. Thresholds are adjusted to get releases through. Reviewers spend less time on individual failures because too many have previously proved meaningless.
The opposite design failure is equally dangerous.
A single aggregate score may improve while a narrow but important behaviour deteriorates. Better answers on routine cases can numerically compensate for a newly introduced failure on a small group of high-consequence cases.
Regression testing therefore has to preserve the identity of important failure modes.
A release that becomes slightly better on average but starts violating a critical business rule has not necessarily improved in a way the enterprise can accept.
The suite needs enough structure to say so.
The regression set becomes a record of tolerated variation
Over time, a strong AI regression suite contains something more useful than a collection of prompts and reference answers.
It records what the organisation has decided may vary.
For one test, several phrasings may be acceptable as long as three required facts remain present. For another, the wording may be unconstrained but a tool-selection decision must remain stable.
Elsewhere, several recommendations may be legitimate, while one prohibited recommendation should block promotion whenever it appears.
Those acceptance boundaries can become more precise as production failures are discovered and added to the regression set.
Production monitoring can later show that a release hurt real task completion; this regression suite serves an earlier purpose, deciding which candidate behaviours should have blocked promotion in the first place.
That is a different role from the broader evaluation pipeline that decides how testing fits into the release process. The regression suite itself is carrying a narrower form of operational knowledge: the difference between variation the business accepts and behaviour it considers broken.
That distinction becomes increasingly important as AI applications acquire more model calls, retrieval steps, tools and generated intermediate decisions. More variable surfaces create more opportunities for harmless differences—and more places where a consequential regression can hide among them.
A useful probabilistic regression suite does not ask the new release to repeat the old release word for word.
It has to recognise when two different outputs are still doing the same job, and when a seemingly small difference means the application no longer is.