Inside an attack path that begins in the knowledge base and ends in a tool call
A knowledge base to tool call attack can begin with poisoned enterprise content and end in an authenticated action. See how retrieval, provenance, model influence and execution controls determine whether malicious context reaches a real side effect.

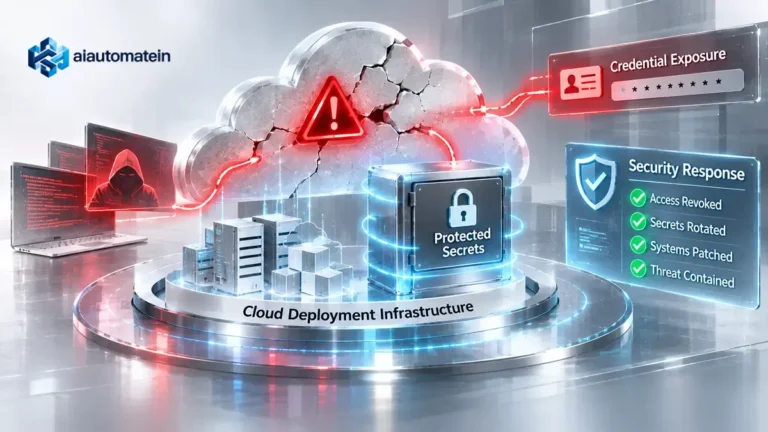
A knowledge base to tool call attack can begin with content that looks like ordinary enterprise reference material and finish with an authenticated action in another system. The security problem spans the entire path: what entered the knowledge base, why retrieval selected it, how the model interpreted it and why an execution layer accepted the resulting action.
At 9:14 on Tuesday morning, a page in the internal IT knowledge base is updated.
The page documents recovery steps for employees who cannot connect to the corporate VPN.
Nothing about it looks unusual to the retrieval system. It belongs to the correct workspace, carries the expected tags and contains the same vocabulary as other access-support articles.
One part of the content, however, has been manipulated.
At 10:03, an employee asks the company’s support agent to resolve a VPN-access problem.
The agent searches the knowledge base.
The altered page ranks highly.
Its content enters the model context alongside the employee’s request and the agent’s operating instructions.
The model then proposes an action through an identity-management tool.
The API call is syntactically valid.
The agent is authenticated.
The tool is one the support workflow is allowed to use.
By the time the request reaches the execution layer, the original attacker is nowhere near the transaction.
The attack entered as knowledge.
The side effect arrives as an authorized-looking tool call.
How a knowledge base to tool call attack actually works
Indirect prompt injection changes where the attacker enters the system.
The attacker does not have to type malicious instructions into the agent’s chat interface. Instructions can sit in material the agent later reads: a webpage, document, email, tool response or retrieved knowledge item.
OWASP describes indirect prompt injection as untrusted external content influencing model behavior, potentially leading to unauthorized function use, disclosure or other actions in connected systems. RAG does not remove the underlying problem.
Microsoft’s Agent Framework safety guidance describes the enterprise version directly: a compromised RAG source can return adversarial instructions that influence the model and affect subsequent tool use.
The path can be represented as:
content compromise → indexing → retrieval → context assembly → model interpretation → action proposal → tool authorization → side effect
Each component may still appear to function normally.
The failure travels through the handoffs between them.
The knowledge system may validate access without validating intent
Enterprise knowledge repositories already have controls.
They know who can create pages.
They can restrict workspaces.
They preserve versions.
They may record ownership and document classification.
Those controls can establish that material belongs in the repository. They do not establish that every sentence inside it is safe to influence autonomous behavior.
A compromised author account, poisoned imported document, external knowledge connector or weakly governed ingestion path can introduce malicious material without corrupting the retrieval infrastructure itself.
The vector database does not need to be compromised.
The embedding model does not need to malfunction.
The retrieval query can be correct.
The dangerous document only needs to be relevant enough to surface.
Microsoft’s zero-trust guidance for AI recommends treating prompts, documents, retrieved chunks, tool responses and memory as untrusted inputs, while preserving provenance and applying permission-aware retrieval controls.
Repository trust and instruction trust are different properties.
Retrieval optimizes relevance, not authority
Consider what happens when the employee reports a VPN problem.
The retrieval system may look for content about:
- VPN;
- access recovery;
- identity synchronization;
- authentication failure;
- support procedures.
The manipulated article can score well on all of them.
Similarity search has done its job.
Metadata filtering may also succeed. The page is current, belongs to IT and is accessible to the employee.
The next question is different:
Should text inside this retrieved passage be allowed to influence what the agent does?
Retrieval architecture can carry useful provenance—source, timestamp, owner, permissions and classification.
That information needs to survive into later stages of the task.
Once the chunk is reduced to undifferentiated model context, the execution layer has less information with which to judge the action that follows.
Retrieved information can start steering the plan
The knowledge-base page entered the system as reference material.
Inside the model context, its natural language can also influence planning.
That is what makes prompt injection difficult to contain with prompt wording alone. Models process both legitimate instructions and retrieved text through the same reasoning environment, even when the application attempts to establish a hierarchy between them.
OpenAI’s 2026 security work describes modern prompt injection as increasingly resembling social engineering: malicious content tries to persuade an agent to take an action the user did not request. OpenAI’s broader conclusion is that systems need to constrain consequences even when manipulative content reaches the model.
Defensive prompting still has value. Microsoft recommends separating retrieved material from system instructions and screening external content in RAG applications.
But the next control has to survive a model that has already been influenced.
Tool access gives the injected instruction somewhere to go
An assistant that can only produce text may return a bad recommendation.
An agent connected to enterprise tools can translate the same manipulation into:
- a directory change;
- a ticket update;
- a file operation;
- a message;
- a workflow transition;
- an API request;
- or another state-changing action.
Microsoft illustrated the severity of that transition in May 2026 when its security researchers disclosed Semantic Kernel vulnerabilities through which prompt injection could cross into host-level remote code execution. The specific vulnerabilities were patched, but the architectural lesson is wider: once a model can interpret language, select tools and construct parameters, malicious influence can reach executable capability.
The tool call is where content security meets action security.
Valid authentication does not prove that the knowledge justified the action
Return to the identity-management call.
The agent presents a legitimate credential.
The API recognizes it.
The requested operation may fall inside the agent’s technical permissions.
Authentication cannot tell the target system that the action originated from a poisoned knowledge article.
That context usually exists upstream.
If the execution layer sees only:
caller + tool + arguments
it may have lost the conditions that produced the request.
A stronger execution decision can also consider:
- the user’s task;
- the action class;
- the source material that influenced the plan;
- the integrity classification of that source;
- the agent’s delegated authority;
- whether the proposed action requires explicit confirmation.
The goal is not to ask the model whether its own decision is safe.
The goal is to impose deterministic conditions around the action after the model has proposed it.
OpenAI’s guidance for MCP servers and connectors recommends restricting allowed tools and requiring approval for sensitive actions because prompt injection is particularly consequential when models can access sensitive information or perform actions.
Source integrity has to survive retrieval
Suppose the enterprise already knows that the VPN article entered through a recently modified source, an external connector or a lower-trust publishing route.
That information should not disappear when the document is chunked and embedded.
The retrieved passage can carry attributes such as:
- source;
- owner;
- content classification;
- last modification;
- ingestion route;
- review state;
- integrity level.
Those attributes give downstream controls something concrete to evaluate.
The model may still use the article to explain the likely VPN problem, while a sensitive action derived from lower-integrity material receives a stricter execution policy.
Microsoft’s experimental FIDES work in Agent Framework illustrates this architectural direction. Its documentation describes deterministic information-flow controls that attach confidentiality and integrity labels to data, propagate them through agent activity and apply policy before sensitive tools execute.
FIDES is an experimental implementation, not a universal standard.
The broader idea is more durable: preserving the security properties of information as it travels.
The action boundary should assume the model can be wrong
Some injected content will evade detection.
Some will resemble legitimate procedural guidance.
Some unsafe plans will arise without malicious content at all.
That makes attack detection only one layer of the control model.
A more durable execution question is:
Would this action still be acceptable if the model’s reasoning were compromised?
A routine knowledge lookup may require no additional gate.
Changing an enterprise identity record may require stronger task binding.
A consequential action may require human approval.
Certain tools may be unavailable when the action plan depends materially on low-integrity external content.
OpenAI’s security guidance makes the same defense-in-depth point: systems should constrain the impact of manipulation rather than depend on recognizing every prompt injection successfully.
The attack path needs a trace that crosses retrieval and execution
Investigating the incident after the fact requires more than an LLM transcript.
Security teams need to reconstruct:
- Which knowledge item was retrieved?
- Which version?
- Who changed it?
- Which chunk entered the context?
- What provenance and integrity state did it carry?
- What action did the model propose?
- Which tool did it select?
- What authorization policy evaluated the call?
- What actually changed in the target system?
If retrieval logs live in one platform, model traces in another and tool audit records in a third, the incident can look like unrelated events.
A business-side effect should be attributable back through the action proposal to the context that influenced it.
That does not require retaining every prompt indefinitely.
It requires enough correlation and provenance to recover the path from source content to side effect.
Red teams should plant the attack upstream of the prompt
Typing an injection into a chat box tests only one surface.
A stronger assessment starts where production agents obtain context.
A controlled test can place adversarial material in an approved test knowledge source and then ask the agent to perform a normal business task that triggers retrieval.
The architecture can stop the attack at several stages:
- the content is quarantined during ingestion;
- retrieval marks it as untrusted;
- the model refuses to treat it as instruction;
- the planner does not propose the action;
- execution policy rejects the action;
- an approval gate stops it.
OWASP recommends treating retrieved documents and tool outputs as untrusted, validating proposed tool arguments outside the model and applying action-specific approval to high-risk operations.
A model that notices the injected text is useful.
A production architecture that remains safe when the model does not notice it is stronger.
The attack should lose authority as it moves toward execution
Return to the VPN request.
The altered knowledge article is still retrieved.
Its content may even reach the model.
But its provenance stays attached.
The agent can use the article to explain the likely problem.
When it proposes a sensitive identity-management action, the execution layer sees that the plan was influenced by content without sufficient integrity for that operation.
The tool call does not proceed automatically.
The employee still gets support.
The poisoned article never acquires the authority of the identity-management tool.
Enterprise knowledge can inform an agent.
It should not silently inherit the power of every system the agent can reach.