When the audit trail contains personal data too
AI observability privacy trace data can expose personal information long after the original workflow ends. See how minimised capture, redaction, access controls and differentiated retention keep traces useful without turning telemetry into a shadow data store.

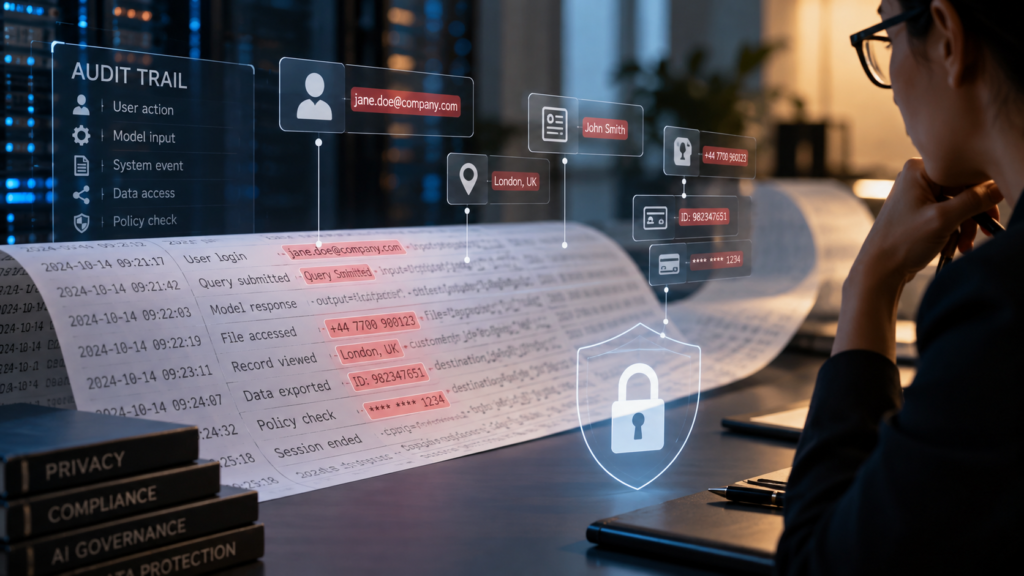
AI observability privacy trace data creates an unusual governance problem: the records collected to explain what an AI system did can contain the same personal information the production workflow was supposed to protect. Prompts, retrieved context, tool arguments, tool results and model outputs can leave a second copy of that information inside tracing infrastructure with different access, retention and operational purposes.
At 2:16 p.m., an employee asks the company’s benefits agent about an incorrect dependent listed on her health plan.
The agent retrieves the employee record.
It checks the benefits platform.
It calls a tool that returns the dependent’s name, date of birth and relationship to the employee.
The correction succeeds.
The HR record is fixed by 2:18.
Two days later, an engineer investigates an unrelated latency problem.
She opens the agent trace.
The trace contains the employee’s original message.
It contains the retrieved record.
It contains the arguments sent to the benefits tool.
It contains the tool result.
It contains the model’s final response.
The production system needed those details for two minutes.
The observability system now has its own copy.
AI observability privacy starts with what the trace actually records
Traditional application traces often work well with operational metadata:
- timestamp;
- service name;
- request ID;
- duration;
- status;
- error;
- dependency;
- resource consumption.
AI systems create pressure to record more.
When something goes wrong, engineers want to know what the model saw, what retrieval returned, which tool was selected and what came back from that tool.
Modern tracing systems can expose those layers.
Microsoft Foundry’s tracing guidance warns that traces can contain user inputs, model outputs, tool arguments and tool results, and recommends minimizing or redacting personal data before it reaches telemetry.
The privacy question belongs at instrumentation design:
Which parts of this operation need to be observable, and which parts need to be copied into observability storage?
Those are separate decisions.
A trace can preserve structure without preserving every payload
Consider the benefits-agent run.
An engineer may need to know that:
- the request entered at 14:16:04;
- retrieval took 420 milliseconds;
- three records were returned;
- the model selected
update_dependent; - the tool call took 810 milliseconds;
- the tool succeeded;
- the second model call took 1.6 seconds;
- the run completed without retry.
None of that requires the trace to retain the dependent’s date of birth.
OpenTelemetry’s GenAI semantic conventions explicitly warn that input and output messages, system instructions, tool-call arguments and tool-call results can contain sensitive information, including PII.
OpenAI’s Agents SDK exposes the distinction directly: tracing can remain enabled while trace_include_sensitive_data=False removes potentially sensitive LLM and tool-call inputs and outputs from the trace payload while preserving spans.
Trace structure can describe the execution.
Trace content can reveal the people inside it.
The second deserves a higher threshold.
Tool traces can carry more personal data than the prompt
Prompt privacy gets most of the attention.
Tool results can be more consequential.
The employee may type:
My dependent information is wrong.
The benefits API may return a substantially richer record.
The same pattern appears elsewhere.
A customer-service agent asks for one order and receives a customer profile.
A finance agent checks one payment and receives account-holder information.
A recruiting agent queries one candidate and receives far more than the user typed.
Privacy review therefore has to inspect the instrumentation around tools, not only chat history.
Microsoft classifies several GenAI telemetry fields as sensitive content, including input and output messages, system instructions, tool definitions, tool-call arguments and tool-call results. Its current preview controls can route that material into a dedicated protected table rather than leaving it alongside ordinary trace telemetry. Microsoft explicitly marks this protected-table capability as preview and says preview features are not recommended for production workloads.
The architectural lesson is useful even where that specific preview feature is not used:
operational trace metadata and content-bearing trace fields do not need the same treatment.
Debugging purpose does not justify unrestricted duplication
Observability has a legitimate purpose.
Teams need to diagnose failures, investigate incidents and monitor performance.
That does not make every available field necessary.
GDPR Article 5 requires personal data to be adequate, relevant and limited to what is necessary for the purpose, and limits identifiable retention to what that purpose requires.
CNIL’s logging guidance makes the operational implication concrete. It recommends recording references to affected data where possible to avoid duplicating personal data in logs and warns against excessive duplication and unlimited retention.
For AI observability, the useful question is not:
Can the tracing framework capture this field?
It is:
What diagnostic question requires us to retain this field?
Instrumentation does not have to imply payload replication.
Redaction after ingestion may already be too late
Suppose the observability dashboard hides the employee’s name.
That improves what the engineer sees.
It does not prove the raw value never entered the telemetry infrastructure.
Before reaching the dashboard, it may already have passed through instrumentation, an exporter, a collector and the telemetry backend.
Microsoft recommends removing or masking personal data, secrets and credentials from prompts, tool arguments and span attributes before they reach telemetry.
That creates a useful order of preference:
- do not capture unnecessary content;
- transform it before export where capture is needed;
- place unavoidable identifiable content behind stronger access and retention controls.
Dashboard masking can help.
It is weaker than collection minimisation.
Sampling reduces volume, not necessarily privacy exposure
Tracing 5 percent of production runs reduces telemetry volume.
It does not decide what is appropriate inside the 5 percent that remain.
A sample can still contain one employee’s health information, one customer’s identity document or one person’s private correspondence.
Sampling is therefore a volume control.
Privacy still requires content control.
A production design might:
- capture latency for every run;
- retain tool name but not arguments;
- retain error type but not the complete response;
- preserve correlation IDs;
- enable richer capture only when a controlled diagnostic investigation requires it.
The control belongs at field and span level, not only at sampling level.
Trace access can be broader than business-data access
The engineer investigating latency may never have been authorized to open the employee’s benefits record.
If that record is copied into a general observability system, the same engineer may nevertheless encounter it there.
This is a quiet privilege expansion.
Production applications often have mature access regimes.
Centralized telemetry may be available to platform engineers, developers, SRE teams, security analysts and vendor support.
Once personal content enters that layer, its audience can change.
Microsoft’s preview protected-table design illustrates one way to separate the two. Sensitive GenAI content can be routed into AppGenAIContent, configured with deny-by-default protection and exposed only to privileged readers, while non-sensitive telemetry remains accessible through ordinary trace access. The capability is currently preview and should be treated as such.
The principle is broader than that implementation:
access to operational telemetry does not automatically justify access to the personal content carried inside an AI interaction.
Retention can quietly outlive the original workflow
Return to the dependent correction.
Suppose the HR conversation is retained for 30 days.
The tracing platform keeps telemetry for 180.
The conversation disappears.
The copied tool payload remains.
Instrumentation has silently extended the personal-data lifecycle.
CNIL’s logging recommendation warns specifically against this failure mode. Where source data has a shorter retention period, logging practices should be adapted so those personal data do not continue to survive inside logs after the original retention period has expired.
CNIL’s 2026 retention guidance also reiterates that personal data cannot be kept indefinitely and that retention must follow the purpose for which the data is processed.
That means:
Telemetry retention: 180 days
is not always a sufficient policy.
Execution metadata may justify one lifecycle.
Raw prompts or tool payloads may justify another.
The trace should know which fields are content-bearing
A useful observability schema can classify more than span type.
It can classify privacy characteristics.
For example:
agent.run.duration
Operational metadata.
tool.name
Operational metadata.
tool.status
Operational metadata.
tool.argument.customer_id
Identifier requiring context-sensitive treatment.
tool.argument.free_text
Potential personal-data content.
tool.result
Potentially high-content personal data.
gen_ai.input.messages
Potential personal or confidential content.
gen_ai.output.messages
Potential personal or confidential content.
OpenTelemetry itself flags several of those GenAI content attributes as likely or potentially sensitive.
Once classification exists, controls can follow.
A collector can drop content-bearing attributes.
Production can disable them.
Privileged diagnostics can enable selected fields.
Retention and access can differ.
Deletion can target the content-bearing store without destroying every operational metric derived from the run.
The instrumentation contract carries privacy meaning instead of relying on every engineer to remember which fields are dangerous.
Production and diagnostic tracing do not need the same content
Full content can sometimes be necessary.
A model repeatedly selects the wrong tool.
Retrieval returns the wrong customer.
A safety incident requires deeper reconstruction.
A tool call appears corrupted.
The engineering team may need more than timing metadata.
That does not justify permanent full-content tracing across all production traffic.
Microsoft currently recommends enabling content recording during development and debugging and disabling it in production where sensitive information could be exposed.
A mature design can formalize two modes.
Normal production mode
- minimal content;
- stable correlation IDs;
- latency and errors;
- model and tool identifiers;
- resource metrics.
Escalated diagnostic mode
- approved incident window;
- narrow service or cohort;
- selected richer fields;
- restricted viewers;
- documented purpose;
- automatic expiry.
Observability depth can increase when the investigation justifies it rather than remaining permanently maximized.
A privacy contract for traces makes the trade-off explicit
AI systems increasingly need a privacy contract alongside the instrumentation schema.
For each trace or span family, record:
- Purpose
What operational or security question does this telemetry answer? - Metadata retained
Which non-content fields are required? - Content permitted
Can prompts, retrieved text, tool arguments, tool results or model responses be recorded? - Transformation
Which fields are dropped, masked, tokenized or pseudonymized before export? - Destination
Which backend receives the trace? - Access class
Who can view metadata, and who can view sensitive content? - Retention
How long does each telemetry class survive? - Diagnostic escalation
Under what conditions can richer capture temporarily be enabled? - Deletion and lifecycle alignment
How will trace content respect shorter retention or deletion requirements attached to the source processing?
This does not reconstruct why a governed business outcome was valid.
It governs the privacy characteristics of telemetry itself.
Observability should fail safely when content is absent
There is an obvious engineering objection.
What if the omitted content is precisely what the team later needs?
Sometimes it will be.
That is why minimised traces still need strong correlation.
A trace can retain:
- run ID;
- span ID;
- source-system object reference;
- model version;
- tool name;
- tool status;
- policy result;
- error code;
- timestamp.
An investigator can then retrieve authoritative information through the controlled source system where policy permits rather than relying on an uncontrolled copy sitting in telemetry.
The principle is straightforward:
retain enough information to locate and correlate the source;
copy the source into telemetry only when the diagnostic purpose genuinely requires it.
That keeps observability useful without turning the tracing platform into a shadow repository of enterprise personal data.
The safest trace can still explain the system
Return to the benefits case.
The engineer opens the trace again.
She can see:
- the run started at 14:16;
- retrieval succeeded;
- one benefits record was returned;
- the first model call completed;
update_dependentwas selected;- the tool executed successfully;
- the second model call was unusually slow;
- the final response completed at 14:18.
She can diagnose the latency problem.
She cannot see the dependent’s name.
She cannot see the date of birth.
She cannot read the employee’s full benefits record.
If a future incident genuinely requires that content, the organisation has a controlled way to obtain it.
The trace still explains the system.
It no longer needs to replay the person’s life to do so.