
Persistent Memory Gives Agents Continuity—and Creates a New Control Surface
Persistent AI agent memory governance determines what information survives beyond a session, how it is revised and which memories return to the model later. See how extraction, consolidation, scope, retrieval and correction shape the durable state that influences future agent decisions.

Introduction
A customer-support agent remembers three things from earlier conversations: the customer prefers morning deliveries, a previous shipment was damaged, and a temporary warehouse closure affected the last order.
The first two facts may still improve the next interaction. The third can mislead the agent if the warehouse has reopened and the remembered disruption is treated as current operating state.
Nothing has to fail inside the memory system for that to happen. It may have preserved exactly what it was designed to preserve.
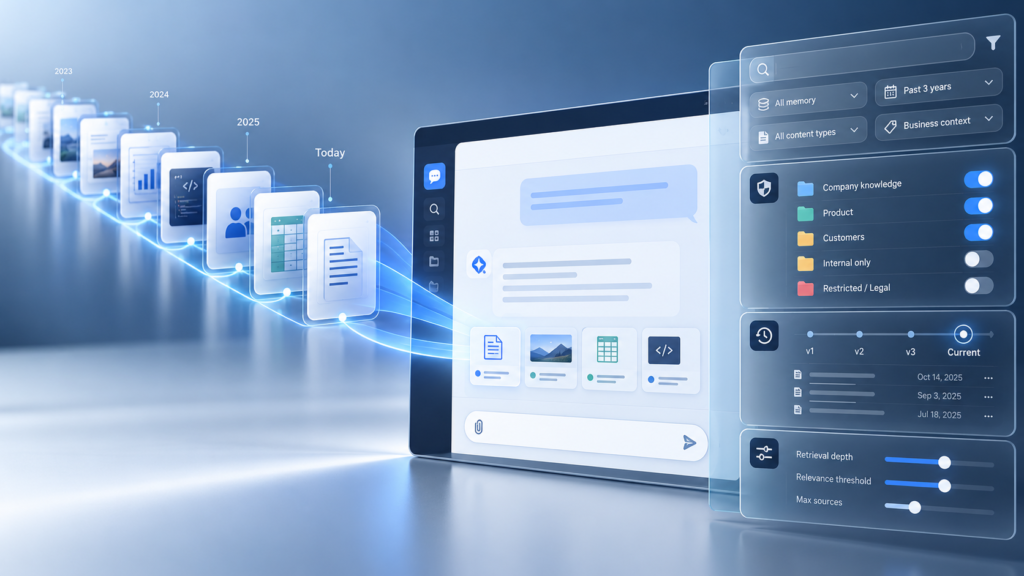
That is why persistent AI agent memory governance is an architecture problem rather than simply a personalization feature. Long-term memory can extract information from an interaction, turn it into durable state, modify that state as new evidence arrives and later decide which memories should return to the model. Information created in one session can therefore influence planning or action long after the circumstances around it have changed.
The resulting control surface is the memory pipeline itself.
At a glance
- Persistent memory is derived state, not simply a longer conversation transcript.
- What enters memory depends on extraction and consolidation logic, which can transform several interactions into a smaller set of durable claims.
- Memory scope and retrieval determine which past information is eligible to enter a later task.
- Revision and correction controls matter because the stored representation can change independently of its original source.
- Fast-changing operational facts should normally remain anchored in authoritative systems rather than being treated as durable agent memory.
Persistent memory is derived state, not an extended transcript
Short-term conversational state primarily answers what happened during the current interaction. Persistent memory has a different purpose: selecting what from earlier interactions is useful enough to carry forward.
Microsoft’s Foundry Agent Service Memory, currently in preview, separates session context from long-term memory that extracts and consolidates information into durable knowledge for later interactions. Microsoft’s current Foundry memory documentation also notes that the Memory Store API is a preview capability whose behaviour may change.
Amazon Bedrock AgentCore Memory makes a comparable distinction between short-term interaction events and long-term memory records produced for future retrieval.
That difference matters because a transcript and a memory record are not equivalent representations. A long interaction may eventually produce a small profile fact, preference, summary or learned pattern. Future sessions may use that derived record without loading the conversation from which it originated.
For enterprise systems, the control question therefore includes the durable representation produced from the interaction—not only whether the original conversation was stored.
What gets written is already a model decision
Useful memory depends on selection.
An interaction may contain ten potentially relevant details while the memory pipeline persists two. Several statements can be compressed into one summary, and repeated behaviour may be interpreted as a preference even when nobody stated that preference directly.
AWS exposes this process through AgentCore memory strategies. Strategies determine what information is extracted from short-term events and how it is converted into long-term records; built-in approaches include semantic facts, preferences, summaries and episodic information.
Microsoft’s preview memory service likewise describes long-term memory as information extracted and consolidated from interactions rather than a verbatim archive. Its memory architecture documentation distinguishes learned durable context from session history.
Consider a customer saying, “Use the London warehouse for this order.”
The transaction contains a legitimate instruction. A memory process that turns it into “customer prefers London fulfillment” has created something different: a reusable claim about future behaviour.
That claim may be sensible. It has still undergone semantic promotion from transaction-specific context into persistent agent state.
Memory governance therefore starts before storage. Enterprises need to know what kinds of observations are eligible to acquire durable meaning.
Consolidation can rewrite the durable record
Persistent memory also has to handle change.
Suppose a customer initially requests delivery before noon. Several months later, they explain that afternoon delivery is now preferable because staffing has changed. Storing both statements forever without reconciliation would leave later retrieval to resolve an avoidable contradiction.
Google’s Memory Bank generation and consolidation model compares newly extracted information with existing memories inside the relevant scope. Depending on duplication or contradiction, the system can create, update or remove memory records.
That means the remembered state is not necessarily a fixed historical fact. It can be a maintained interpretation of accumulated interactions.
For higher-consequence enterprise use, the history of that interpretation may itself matter. Google’s Memory Bank revision model preserves revision snapshots when memories change and supports inspection of earlier states and rollback.
A reviewer may therefore need more than the current value of a memory. Useful evidence can include what the agent remembered when an earlier decision occurred, which interaction caused a later change and whether that change came from new information, consolidation or an explicit correction.
The objective is not to preserve every prompt indefinitely. It is to retain enough history to reconstruct the derived state that actually influenced the agent.
Scope determines which history is eligible
A persistent-memory system also needs an explicit answer to a basic question: whose past is this?
A customer-service agent may need account-scoped memory. An internal assistant may need employee-level state. A project agent may require information isolated to a workspace or engagement. Some applications will need more than one dimension because a global user preference and knowledge acquired inside a confidential project should not share the same retrieval boundary.
Microsoft’s memory API requires application-defined scope to partition durable memories. Its Foundry memory documentation describes scope as the boundary used to organize memories.
Google’s Memory Bank similarly maintains isolated memory collections by scope, while AWS documents actor-, session-, strategy- and custom namespace dimensions for organizing long-term AgentCore memory.
The exact scheme is application-specific, but the consequence is architectural: memory scope decides which history is even eligible to appear in the current interaction.
A mistake in that boundary is not merely poor personalization. It can put one customer’s state, one employee’s context or one project’s information into another task.
Retrieval decides which stored state reaches the model
A memory can exist without being used.
Before it influences an agent, something has to retrieve it and insert it into the working context. AWS supports semantic retrieval over long-term AgentCore records; Google Memory Bank provides similarity-based search within the relevant scope; Microsoft’s preview memory service retrieves profile, summary and other durable context for later interactions. AWS documents long-term memory retrieval here, while Google documents Memory Bank retrieval and scoped memories here.
This introduces a failure mode that storage checks alone cannot catch: the memory may be accurate as history and still be inappropriate for the task now.
An account-management agent might correctly remember a discount preference from a previous negotiation. The fact remains historically true, but inserting it into a new pricing decision after contract conditions have changed could bias the task.
Semantic similarity is therefore only one possible retrieval signal. Depending on the application, useful controls may also consider memory type, scope, age, confidence, sensitivity and whether the information represents a durable preference or mutable operational state.
The behaviour of the agent depends less on everything stored than on the subset permitted back into working context.
Persistent memory should not impersonate the system of record
This boundary is particularly important in enterprise applications.
An agent may reasonably remember that a customer prefers quarterly reviews, that a project uses a particular reporting format or that a user rejected one implementation option in an earlier discussion. The value of those facts comes from continuity across interactions.
An account balance, inventory quantity, active policy version or supplier payment instruction has a different lifecycle. Those facts can change independently of the conversation that originally exposed them.
If an agent stores “800 units available” as long-term memory, the record can remain intact while inventory falls to 40. A remembered approval threshold can sound authoritative even after finance has published a new policy.
Microsoft makes a related distinction in its Foundry memory guidance, positioning memory around learned persistent user or agent context while pointing to grounding and knowledge capabilities for curated organizational information.
Transactional systems make the separation even more consequential. Current balances, stock, policy status and payment instructions should normally be re-read from the systems responsible for maintaining them.
Persistent memory is strongest when it carries context whose usefulness comes from continuity. It should not acquire authority merely because an older value is easy to retrieve.
A correction has to reach durable state
Correcting the agent in conversation does not guarantee that its long-term memory has changed.
An employee can tell an HR assistant, “I no longer work from the Singapore office,” receive an accurate response and still encounter the old location in a later session if the durable profile was never updated.
Memory platforms increasingly expose direct lifecycle operations because these two events are separate. Microsoft’s preview Foundry memory service supports item-level management and explicit remember-or-forget operations through its memory interfaces. Google Memory Bank supports memory creation, update, deletion and revision history through its managed memory model.
An enterprise application therefore needs to know which kinds of user correction should update persistent state, which require review and which should cause the agent to query an authoritative source instead.
Otherwise the model can understand a correction perfectly for one interaction while the system continues reintroducing the obsolete memory later.
Durable memory lengthens the blast radius of bad input
Persistent memory also changes how long faulty information can matter.
A misleading statement in ordinary session context may disappear when the conversation ends. If the same information is promoted into long-term memory, it can influence later sessions in which the original input is nowhere to be seen.
Microsoft’s Foundry memory security guidance explicitly identifies prompt injection and memory corruption as risks because incorrect or harmful stored information can affect future responses and actions.
A poisoned memory does not need to contain an obvious malicious instruction. It can be an invented preference, an obsolete operating constraint, an incorrect project fact or a manipulated summary that later re-enters context as apparently established knowledge.
That makes controls around extraction and consolidation relevant to security as well as quality. Restricted write paths, scoped access, review of generated memories, revision history and correction mechanisms all help prevent one bad interaction from gaining a durable place in future reasoning.
The original conversation can disappear from working context while its derived state continues to affect later decisions.
Govern the memory pipeline, not only the store
Storage security and retention remain important, but persistent-memory governance spans a longer chain:
interaction → extraction → consolidation → durable state → scope → retrieval → model context → action
Each transition can change what the agent carries forward.
Extraction can preserve the wrong observation. Consolidation can merge facts that should remain separate. Scope can admit history from the wrong entity or workspace. Retrieval can surface a valid but obsolete memory. The model can treat remembered context as authoritative current state, and a conversational correction can fail to update the durable record.
Current platforms expose these stages through different combinations of extraction strategies, consolidation logic, namespaces or scopes, retrieval APIs, revision history and memory-management operations. Microsoft Foundry, Amazon Bedrock AgentCore and Google Memory Bank already make much of this pipeline visible to application architects.
The enterprise design decision is how those mechanisms should behave for different kinds of memory.
A preference, a project summary, a learned procedure and a mutable operational fact do not deserve identical treatment merely because all four can be serialized into a memory store.
FAQs
What is persistent AI agent memory?
Persistent AI agent memory is information retained beyond the current interaction and made available to later sessions. It usually contains distilled or structured knowledge such as preferences, summaries, learned facts or recurring context rather than the entire original conversation.
Why does persistent memory create a new control surface?
Because the memory system can influence what durable information is created, how conflicting memories are reconciled, which entity or workspace owns the memory and what stored state returns to the agent later. Those operations can change future behaviour without changing the underlying model.
Should an AI agent store business data in long-term memory?
Selectively. Durable preferences, learned context and historical summaries can be useful. Fast-changing authoritative facts such as balances, inventory, policy values or payment instructions are generally safer when retrieved from the systems responsible for keeping them current.
What is memory consolidation?
Memory consolidation reconciles newly extracted information with memories that already exist. Depending on the implementation, the system may create a new record, modify an existing one, merge overlapping information or remove a memory contradicted by newer evidence.
How should enterprises govern AI agent memory?
Governance should cover extraction, consolidation, scope, retrieval, correction, revision and the boundary between remembered context and authoritative operational data. Protecting the underlying storage system addresses only one part of that lifecycle.
Continuity depends on controlling what survives
Persistent memory makes an agent more useful because each session does not have to begin from zero. The trade-off is that information created during one interaction can enter later planning after several transformations: extraction, consolidation, revision and retrieval.
By then, the original conversation may be distant from the state influencing the decision.
A durable memory system therefore needs to make clear what survived, how that state changed, where it is eligible to appear again and whether the agent is looking at remembered context or current authoritative data.
Continuity is valuable only when the system can govern what it carries forward.