
Document AI Can Read Every Page It Receives and Still Miss the Missing Page
Document AI completeness validation identifies when a case is missing required evidence even though every received page was processed correctly. See how expected evidence sets, case-specific requirements, waivers and completeness states can prevent incomplete document packets from reaching downstream decisions.

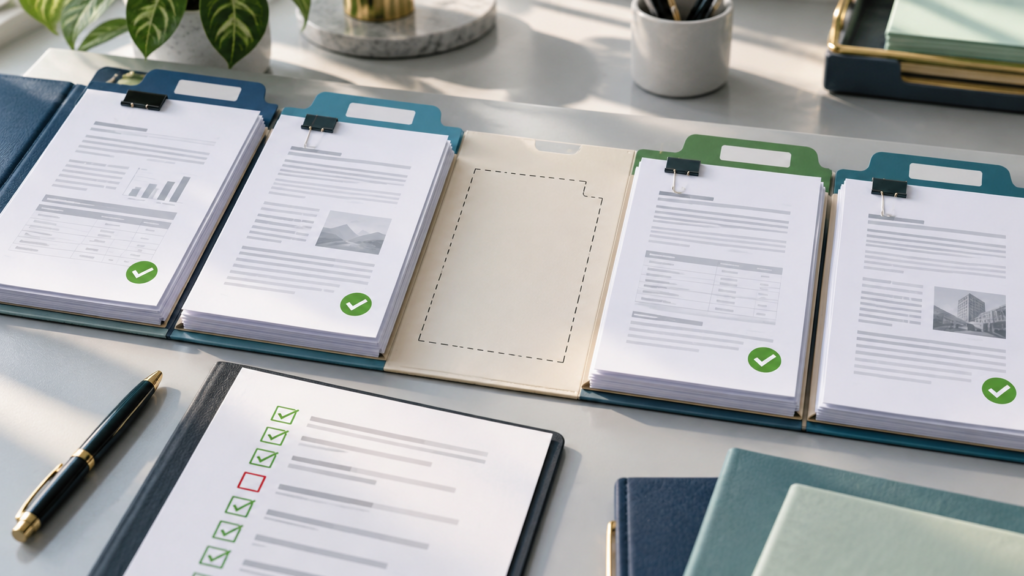
Document AI completeness validation has to answer a question extraction metrics cannot: whether the system received all of the evidence the business process expected in the first place. A processor can read every available page correctly while an incomplete packet moves downstream looking complete.
A lending workflow receives a fourteen-page application packet. The pages are legible, document types are identified correctly, and names, dates and financial values are extracted without an obvious exception.
Nothing in the processing result looks broken. But one required document was never submitted.
There is no poor OCR result to flag. No low-confidence field points a reviewer toward the problem. The processor can be correct about every page it saw because the failure sits outside those pages.
The missing page has no confidence score.
Document AI completeness validation starts with what should have arrived
Most document-processing quality measures begin with the material presented to the system.
Was the document classified correctly? Were the right fields found? Was the extracted value accurate? Did the processor split a composite PDF into the correct logical documents?
Those questions all operate on evidence that has already reached the pipeline.
Google Cloud’s Document AI documentation illustrates the boundary. Its custom splitter identifies individual logical documents inside a composite file; Google uses a mortgage package containing items such as an application, income verification and photo identification as an example. The splitter output identifies which pages belong to each detected document.
That establishes the structure of the material received.
Suppose a particular lending case should contain an application, proof of income, identification and a signed authorization. The system receives the first three. Classification can be flawless, and extraction can be flawless. The case is still missing evidence required by the process.
The workflow needs an expectation against which the received evidence can be tested.
The missing document has no extraction error
Document AI evaluation naturally focuses on observable content.
Google, for example, evaluates processor performance using metrics such as precision and recall by comparing predicted entities against annotations in test documents.
That is appropriate for measuring what the processor found in the material available to it. A runtime case can still fail before any extraction-quality measure becomes useful.
A damaged page may produce weak OCR or uncertain extraction. A required page that never arrives produces neither. There is no document object from which the missing information could be extracted.
Poor extraction may call for image remediation, another model or human verification. An absent document may require a request back to the applicant, supplier, customer or case owner. A document that is legitimately unnecessary needs a recorded business reason rather than repeated collection attempts.
The system therefore needs to distinguish bad evidence from absent evidence.
A human reviewing a familiar paper file often notices that an expected form or attachment is missing because they understand what a complete case normally contains. An automated pipeline will only make the same judgment if that expectation exists somewhere in the process.
Expected evidence has to come from the case, not the packet
A fixed checklist will not always be enough. Required documents can change with the case.
A business customer may need a different evidence set from an individual. A claim above a certain value may trigger additional documentation. Product, transaction type, jurisdiction or risk profile can alter what must be present before work continues.
Completeness therefore depends on more than page count. The case needs some representation of its expected evidence set.
The document processor can report what it observed: document classes, pages, extracted entities and other signals. Case rules supply the expectation against which that observation is compared.
Google’s Document AI validation and correction functionality, currently documented as private preview, points toward part of this model, although it operates primarily on processing results. It allows organisations to define business rules over extracted entities and test consistency across multiple documents. Its validation result model can also distinguish an invalid result from one that is not applicable.
The enterprise requirement is broader.
A case should be able to distinguish between evidence that is still outstanding, evidence that has been deliberately waived and evidence that does not apply under the governing rules.
Completeness should become a workflow state
Many IDP pipelines expose document status in terms such as processed, extracted, validated or reviewed. None of those necessarily means complete.
A packet may be processed successfully while one required document remains outstanding. It may pass field-level validation even though the evidence set needed for the business decision is incomplete.
Completeness therefore deserves an explicit place in workflow state.
Before a case moves into underwriting, claims adjudication, onboarding, compliance review or another downstream decision, the system should be able to establish which expected documents were observed, which remain outstanding and why any requirement has been waived or marked not applicable.
That changes where human intervention occurs.
A reviewer can be brought in because the case state is incomplete or ambiguous, even though every document actually processed performed well.
It also changes operational measurement.
A document team might report strong classification and extraction performance while the business process continues to experience rework because cases reach downstream teams without required evidence.
A more useful operational measure may be the percentage of cases that reach a decision stage with their required evidence set satisfied.
That metric reflects whether the document workflow delivered a decision-ready case, not merely whether individual fields were extracted correctly.
The real control sits before the downstream decision
As document AI becomes more capable, increasing extraction accuracy can make the workflow appear more reliable than the case itself actually is.
The more consequential control sits at the point where a case is allowed to move forward.
Has the required evidence arrived? Are outstanding items understood? Have exceptions or waivers been recorded? Is the evidence set sufficient for the next decision?
Those questions belong to the workflow around the processor.
A system that can read every page it receives is useful. A system that knows when the case should have contained another page is considerably safer.