
Production AI has outgrown the old MLOps boundary
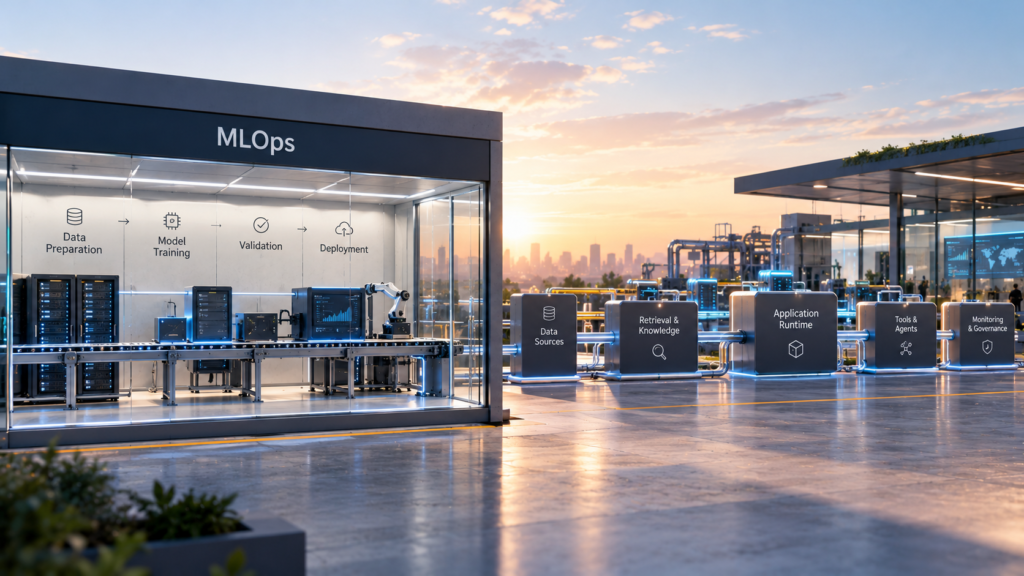
Modern MLOps generative agentic AI expands production discipline beyond the model lifecycle. It brings prompts, retrieval configuration, tools, orchestration, evaluation baselines and execution traces into the versioning, testing, release and recovery boundary.

Introduction
The model has not changed.
Its endpoint is healthy. Latency is normal. Infrastructure alarms are quiet.
Yet an enterprise support agent that worked yesterday is now giving noticeably worse answers.
The cause may sit somewhere outside the model deployment: a prompt alias moved to a new version, retrieval started returning different documents, a tool schema changed, an agent instruction was edited or a production dependency began behaving differently.
No model retraining occurred.
No new model artifact was promoted.
A conventional model-centric release history may therefore show very little.
That is the operating problem behind modern MLOps for generative and agentic AI.
Production AI is increasingly assembled from models, prompts, retrieval, tools, evaluation logic, runtime state and external services. The model lifecycle still matters, but it no longer describes the entire production system that has to be versioned, tested, released, observed and recovered.
MLOps has not become irrelevant.
Its boundary has become too small.
At a glance
- Traditional MLOps created discipline around the model lifecycle, from reproducible development and evaluation through deployment and production operation.
- Generative and agentic applications introduce production components that can change independently of the model, including prompts, retrieval configuration, tool definitions, agent instructions and application logic.
- A release can therefore alter system behaviour while the underlying model version remains fixed.
- Production teams increasingly need enough configuration lineage to establish which model, prompt, retrieval setup, tools and surrounding application were active together when a behaviour occurred.
- Modern MLOps extends familiar lifecycle discipline across that larger production object.
The old MLOps boundary solved a real problem
The original MLOps operating model emerged because machine-learning teams needed a reliable route from experimentation to production.
Training data and features had to be reproducible. Models needed identifiable versions. Candidate performance had to be evaluated before promotion, deployments controlled and production behaviour monitored for failures or deterioration.
A model registry created a durable relationship among the artifact, its metadata, its lifecycle state and its deployment.
For many predictive ML systems, the trained model was also the most important behavioural artifact being promoted.
The surrounding application called it and received a prediction or score. A material change in the system’s intelligence often came from a different model, different features or a changed data distribution.
Generative AI has loosened that relationship.
The model can stay fixed while the application changes substantially.
A production AI release can happen without a model release
Consider an internal procurement assistant running on a fixed foundation-model endpoint.
Version 12 of its prompt says that preferred suppliers should be prioritised when several eligible vendors satisfy a request.
Version 13 removes that instruction during an apparently minor prompt cleanup.
The underlying model stays the same.
So does the deployment endpoint.
The application begins recommending suppliers differently.
From a production-management perspective, something important was released.
Databricks’ current MLflow 3 Prompt Registry reflects this directly. Prompt templates can be independently versioned and assigned aliases such as staging or production. Deployed applications can resolve a prompt through the alias, so changing the alias can move another prompt version into production without redeploying the application code.
The release unit is already wider than the model artifact.
Investigating changed behaviour may require knowing which prompt version ran with which model version.
A model registry by itself cannot answer that.
Retrieval adds another independently changing production surface
A retrieval-augmented application widens the boundary again.
Its behaviour depends partly on what information is available and how that information reaches the model.
Source documents can change or disappear. Chunking, embedding configuration, ranking and access filters can be altered. An index can be rebuilt. Retrieval parameters can move.
Any of those changes can modify the evidence shown to the model without a model deployment taking place.
Structured retrieval creates the same operating problem. An assistant may encounter a changed schema, semantic view or metric definition while every model parameter remains unchanged.
The retrieval configuration and the evidence supplied to the model are therefore part of the production state of the application.
Production lineage has to extend far enough to reconstruct that state.
Tools make configuration capable of changing business behaviour
Agentic systems widen the production object again because software outside the model becomes part of execution.
An agent may query inventory, open a ticket, update a CRM record, send a message or invoke another enterprise service.
Tool definitions determine which operations are visible to the agent and how those operations are described and invoked.
A change to a parameter schema, description, destination or permission can alter application behaviour even when the model and prompt remain untouched.
Microsoft Foundry’s agent telemetry reflects this broader execution object by representing agent operations, run steps and tool calls in traces. Its OpenTelemetry-based conventions also include spans for tool execution and memory operations.
The model invocation has become one event inside a larger application run.
That larger run is increasingly what production teams have to operate.
Production state is becoming more composite
This changes the answer to a basic question:
What version is in production?
For a model-serving workload, identifying the deployed model may once have been a useful shorthand.
A generative or agentic application may also depend on a prompt version, retrieval configuration, tool definitions, orchestration code, policy configuration and an evaluation baseline.
Those objects do not all need to share one artificial version number.
They do need enough lineage that a production behaviour can be connected to the configuration that produced it.
Otherwise, a team can know exactly which model was running and still be unable to reproduce the application.
Evaluation has moved above the model layer
Traditional model evaluation often concentrated on properties such as accuracy, precision, recall, calibration or prediction error.
Those measures remain appropriate for many workloads.
Generative applications frequently need another evaluation layer because the model is only one contributor to application quality.
A fluent answer can still be unsupported by retrieved evidence. An agent can reach an acceptable final answer through an unsuitable tool path. A conversational system may perform well on isolated responses and poorly over a longer interaction.
Current MLflow 3 tooling reflects the wider evaluation object. It supports evaluation of prompts, LLM applications and agents using datasets, built-in or custom scorers, multi-turn evaluation and production traces.
Microsoft Foundry similarly supports evaluation targets that include models, agents, datasets and production traces, while Google’s agent-evaluation tooling can assess deployed agents on final-response quality, tool use, hallucination and safety.
The evaluation target is increasingly the behaviour produced by the assembled application.
That has an immediate operating consequence: prompt, retrieval or tool changes cannot fall outside release control simply because the model artifact did not change.
The detailed design of those release gates is a separate problem. The foundational requirement is to recognise the change as a production change in the first place.
Production traces are becoming part of the engineering record
Endpoint telemetry still matters.
It can show latency, errors, resource consumption and availability.
A compound AI application may also need a record of how execution moved through its major components.
MLflow Tracing, for example, can record activity across models, retrievers, tools and sub-agents along with inputs, outputs and operational metadata.
That capability matters here because the production object is no longer represented completely by the model endpoint.
A trace can provide evidence that a particular application run passed through a particular combination of components.
How teams use those traces to diagnose task quality or reconstruct a specific failed execution deserves deeper treatment elsewhere.
For the MLOps boundary, the important shift is simpler: execution evidence has become part of the production record.
Rollback is no longer always “deploy the previous model”
Rollback becomes more complicated for the same reason.
If behaviour deteriorated after a prompt change, reverting the model does nothing.
If a retrieval index changed, restoring an old prompt may not help.
If an agent began failing after a tool contract changed, the problem may sit outside both.
Production recovery therefore has to target the component that introduced the behaviour change.
Prompts need identifiable versions when they can materially affect behaviour. Retrieval configurations should be reproducible. Tool definitions need controlled change. Application orchestration should follow ordinary software-release discipline.
The model remains a critical dependency, but it is one versioned dependency among several.
External models make reproducibility less self-contained
Foundation-model APIs introduce another departure from many internally trained ML systems.
The enterprise may not own the model artifact at all.
It selects a provider, model family and API surface while controlling the application built around them.
Reproducibility therefore depends heavily on the state the enterprise can preserve itself: provider and model identity, application configuration, inputs, evaluation evidence and observed behaviour.
If a provider changes the behaviour of a model, the organisation still has to determine how its own workload was affected.
Possessing the model weights cannot be the prerequisite for maintaining a useful production history.
The surrounding system has to carry enough evidence of its own.
Modern MLOps connects several engineering disciplines
The expanded boundary also changes ownership.
Data scientists may still own models and evaluation work, while platform engineers manage deployment foundations and application teams own substantial parts of orchestration and prompt behaviour. Data teams can own retrieval or semantic dependencies; security teams control parts of the executable environment; domain specialists define acceptable outcomes; operations needs enough visibility to investigate the assembled workload.
Creating another organisational silo for every new acronym would not solve the underlying problem.
The useful step is to make production responsibility follow the components that can materially change system behaviour.
A prompt edited through a UI is still production configuration.
A retrieval index is a runtime dependency.
A tool schema belongs to the executable environment of an agent.
An evaluation baseline helps explain why a particular configuration was considered acceptable to release.
Each deserves engineering discipline proportionate to its effect on the system.
What belongs inside the expanded MLOps boundary?
A useful distinction is between everything the application uses and everything operations need to control or reconstruct.
The second set is smaller.
| Production object | Why operations may need it |
|---|---|
| Model/provider version | Establish which model behaviour was available |
| Prompt/instruction version | Reproduce behavioural configuration that can change independently |
| Retrieval configuration | Reconstruct the evidence environment presented to the model |
| Tool definitions | Establish the executable capabilities available to an agent |
| Application/orchestration version | Reproduce control flow around model calls |
| Evaluation baseline | Show what quality threshold justified the configuration |
| Execution trace | Connect a production run with the components that participated in it |
Not every implementation detail needs to become a registry entry.
The boundary needs enough information to answer three practical questions:
What changed?
What was running together?
Can we reproduce or reverse the behaviour?
If answering those questions requires manually reconstructing the application from several disconnected systems, the production boundary is incomplete.
MLOps is expanding rather than disappearing
Terms such as LLMOps and AgentOps exist because new operating problems have appeared.
They can be useful shorthand.
The durable architectural change is that production AI has become a compound system.
Traditional models still require data lineage, controlled deployment, evaluation and monitoring. Generative applications add independently changing prompts and retrieval behaviour. Agents introduce tools, multi-step execution and additional runtime configuration.
The precise failure surfaces of MLOps, LLMOps and AgentOps deserve their own treatment.
At this foundational level, the requirement is simply to stop using the model registry as the edge of production responsibility.
The application extends beyond it.
FAQs
What is modern MLOps?
Modern MLOps extends the operating discipline developed for machine learning to AI systems whose behaviour depends on more than a trained model. That may include prompts, retrieval configuration, tools, orchestration, evaluation baselines and runtime evidence alongside conventional model and data lifecycle management.
Why is traditional MLOps not enough for generative AI?
Traditional MLOps remains useful, but generative applications can change behaviour without retraining or redeploying the model. Prompt changes, retrieval updates, tool changes and application configuration may all alter production outcomes and therefore need their own engineering discipline.
Is LLMOps replacing MLOps?
No single terminology has to replace MLOps. LLMOps describes concerns that became more visible with language-model applications, while MLOps continues to cover important model-lifecycle practices. In practice, the disciplines overlap.
What changes when AI agents enter production?
Agents introduce tool use, multi-step execution and additional runtime configuration around the model. Production teams therefore need to manage more of the surrounding application state and preserve enough evidence to understand which components participated in a production run.
What should enterprises version besides the model?
The answer depends on the system, but prompts or instructions, retrieval configuration, orchestration code and tool definitions are common candidates when they can materially change behaviour. Evaluation baselines and traces provide additional evidence about the configuration and its production performance.
The production unit is now the AI system
MLOps gave enterprises a disciplined answer to a difficult question: how do we make machine learning reproducible and operable after experimentation ends?
The problem remains.
Production AI has added more things that can change around the model.
A model may stay fixed while its prompt, evidence, tools or surrounding application move underneath it. Production discipline has to follow those components when they materially affect behaviour.
The old question—
Which model version is deployed?
—still matters.
It is now accompanied by another:
Which combination of model, context, instructions, tools and application logic produced the behaviour we are seeing now?
That is the boundary modern MLOps increasingly has to manage.