
LLM Document Extraction Changes What Counts as Evidence
LLM document extraction evidence trail becomes more important when structured values are inferred rather than copied directly from a page. See how source grounding, extraction method, schema instructions, model identity and configuration state preserve the provenance behind each field.

Introduction
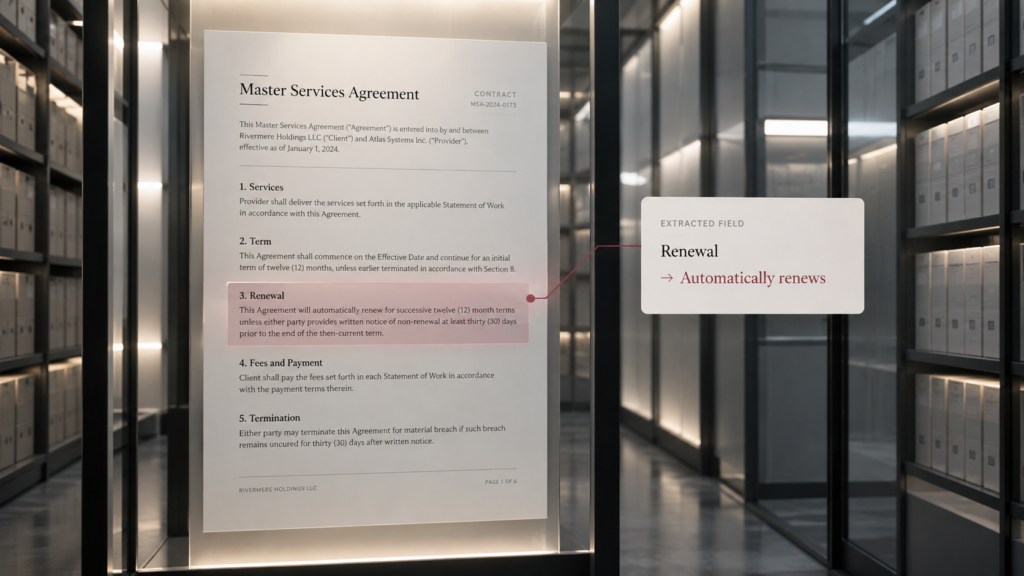
A procurement team asks a document model to extract one field from a contract:
Automatic renewal: Yes / No
The agreement never says:
Automatic renewal: Yes
Instead, a clause states that the contract continues for successive twelve-month terms unless either party gives written notice at least 90 days before expiry.
The model returns:
Yes
The answer may be exactly what procurement needs, but it is a different kind of extraction result. There is no literal Yes to point to on the page. The model has interpreted a clause, applied the meaning of the requested field and produced a structured value that the document itself never states in that form.
This capability is becoming explicit in enterprise document platforms. Google’s Custom Extractor distinguishes fields that are directly extracted from source text from Derived fields populated through inference or generation. The Derived-field capability is currently Preview and subject to Google’s Pre-GA terms. Microsoft’s Content Understanding distinguishes extract, classify and generate methods for document fields, while Amazon Bedrock Data Automation distinguishes explicit from inferred extraction.
That flexibility is one reason LLM-based document processing is useful, and it also changes the LLM document extraction evidence trail.
For a literal field, evidence can often be represented as: this value came from this span on this page.
For an inferred field, that may no longer be enough.
The enterprise has to know whether the value was copied, classified, normalized, calculated or inferred; what source material supported it; what field instruction defined the interpretation; and which extraction configuration produced the result.
The structured value remains important. Its provenance contract is no longer the same.
At a glance
- Generative document extraction can return useful values that never appear verbatim in the source.
- Directly extracted and inferred fields should not share the same provenance semantics.
- A prompt, schema description or field instruction can become part of the production extraction logic.
- Source grounding remains valuable, but for inferred fields it may describe supporting evidence, not the literal location of the returned value.
- Model and extraction-configuration identity matter when an enterprise later needs to reproduce or challenge the field.
Some extracted fields no longer exist on the page
Traditional field extraction creates an intuitive evidentiary relationship.
The invoice says:
Invoice Total: £14,820
The system returns:
14820
Even if normalization removes the currency symbol or changes the number format, the underlying value can still be connected to a specific piece of source text.
Generative extraction expands that field contract.
Google’s current Custom Extractor provides Preview Derived fields whose values can be populated through inference or generation from document context rather than direct text extraction. Google’s examples include deducing a country from an address, counting items in a table and inferring a currency code from contextual signals.
Microsoft Content Understanding makes a comparable distinction. Its document analyzer can use extract for values present in the source, classify for predefined categories or generate for values produced through generative interpretation of the content.
That changes what an enterprise means when it says a field was “extracted.”
Consider:
Renewal type = Automatic
Currency = CAD
Contract risk = High
Insurance requirement satisfied = Yes
Each can be a legitimate structured output without corresponding to one literal string on one page.
The data contract therefore needs to preserve the method by which the field came into existence. Otherwise downstream systems can receive an inferred conclusion with the apparent provenance of a copied fact.
Source grounding means something different for an inferred field
A source location remains useful even when the value is generated, but its evidentiary meaning changes.
For a directly extracted invoice number, a bounding region can answer:
Where did this value come from?
For an inferred renewal classification, the more accurate question is:
Which source material supports this interpretation?
Current platforms expose that distinction differently.
Google says directly extracted fields can populate textAnchor and pageAnchor, while its Preview Derived method does not populate those anchors because the value is inferred rather than directly present in the text.
Microsoft has taken a different approach in Content Understanding. Its current document APIs can provide confidence and source grounding for extract, classify and generate fields. Grounding identifies source regions associated with the returned field, including page and spatial information.
The difference reveals an architectural issue rather than a contradiction between products: there is no single provenance shape for an inferred field.
Sometimes the output is a literal value with a source span. Sometimes it is an interpretation supported by one clause. Several regions may collectively justify the answer, or the inference may depend on document-wide context that cannot honestly be presented as though one phrase were the returned value.
An enterprise evidence model has to preserve those differences.
The extraction instruction has become part of the logic
Generative extraction moves more business meaning into natural-language configuration.
Google’s Custom Extractor supports schema descriptions and prompting that guide how derived fields are interpreted. Google’s Derived-field guidance specifically recommends clear instructional descriptions because they guide the model’s derivation task.
UiPath’s Generative Extractor API makes the relationship particularly visible: a request can define individual field prompts such as asking the system to extract an invoice number or identify the invoice date.
Amazon Bedrock Data Automation uses the same general pattern in its blueprints. Each requested field can carry a natural-language instruction defining what the field represents and how it should be interpreted. AWS also distinguishes an Explicit inference type, where the value should be taken directly from the document, from Inferred, where the value should be inferred from information in the document.
A schema change can therefore be a logic change.
Suppose a contract field initially says:
Does the agreement renew?
and later becomes:
Does the agreement renew without affirmative action by both parties?
The field name may be unchanged and the output type may still be Boolean, but the business meaning supplied to the model has narrowed.
If the enterprise stores only the final true, it loses part of what defined that result.
For generative extraction, the prompt or schema instruction is not merely developer documentation sitting beside the system. It can be executable interpretation logic.
A field needs the configuration that produced it
This does not mean every prompt should be copied into every downstream transaction table.
It does mean the extraction result should remain linkable to the configuration under which it was produced.
AWS provides a useful implementation pattern through Bedrock Data Automation blueprints. Blueprints define requested fields, instructions and extraction logic, and AWS allows organizations to create immutable blueprint versions. A published version preserves a snapshot of the configuration and extraction logic that can be referenced during processing.
The runtime blueprint representation also carries a blueprint identifier and version.
That matters when two runs of the same document return different values because an investigator needs to establish whether they actually used the same extraction contract.
Was the schema identical?
Was the field instruction identical?
Was the same extraction method used?
Was the same published configuration active?
Neither the document nor the final output can answer those questions on its own.
In LLM document extraction, configuration state becomes part of reproducibility.
Model identity matters without turning provenance into regression testing
A second piece of extraction state is the model or processor behind the result.
Generative document platforms increasingly make that state visible.
UiPath’s current IXP documentation describes prompt-driven extraction for unstructured and complex documents, the ability to save and compare model versions, and configurable model settings. Current model configuration includes choices such as model family/version and advanced settings including temperature and seed.
The evidence implication is narrow.
A field such as:
Automatic renewal = Yes
is better understood when its extraction record can be associated with the processor or model configuration that produced it.
This article does not need to turn that requirement into a model-regression framework. The provenance requirement is simpler:
model identity is part of field evidence when model behaviour contributed to the field.
Without it, reproducibility depends on an assumption that “the document extractor” is a stable, singular thing.
In production, it may not be.
Confidence does not explain the inference
Generative extraction systems can attach confidence to fields, but confidence and provenance answer different questions.
Microsoft Content Understanding can provide per-field confidence together with grounding for document fields using extract, classify and generate.
A confidence score can help an application decide how cautiously to treat the result. It does not explain what kind of result it is.
0.94 does not reveal whether the value appeared verbatim on the page, whether the model classified several clauses into a category, whether an observed value was normalized, or whether the system inferred a new value from context.
Even at high confidence, those are different evidentiary states.
At the extraction layer, the useful control is therefore to preserve provenance type alongside confidence, so downstream consumers know what the score is attached to.
Inferred fields should not masquerade as literal fields
Consider two fields:
Country = Canada
and
Country = Canada
They look identical.
In one case, the document explicitly says:
Country: Canada
In the other, the document contains a Toronto address and provincial information, and the model infers the country.
The structured value may be correct in both cases, but the evidentiary basis is different. That can affect validation, auditability and downstream use.
A workflow might allow a directly observed country value to pass automatically while requiring additional confirmation for an inferred jurisdiction. A contract-analysis system might show the clause supporting a generated classification rather than implying that the classification itself appeared on the page. A quality-control process might also evaluate literal extraction and inference using different test criteria.
The schema therefore benefits from treating provenance as a field property rather than an afterthought.
The useful question is no longer simply:
What value did the model return?
It is:
What kind of evidence does this value represent?
The extraction-stage evidence record can stay compact
There is a temptation to respond by logging everything.
That creates volume without necessarily creating usable evidence.
For LLM-based extraction, a compact field-level evidence record can answer a smaller set of questions:
- Source: Which document and document version was processed?
- Field: Which schema field was requested?
- Method: Was the result extracted, classified, generated, derived or inferred?
- Value: What structured result was returned?
- Grounding: What source span or regions support it, when grounding is available?
- Instruction: Which prompt, field description or schema version defined the requested interpretation?
- Execution identity: Which processor/model and relevant extraction-configuration version produced it?
- Confidence or quality signal: What reliability signal accompanied the result, where the platform provides one?
That is not a complete evidence chain for every downstream business action, and it deliberately stops at the extraction boundary.
A later decision may combine the field with rules, master data, other documents, human approvals and system actions. Reconstructing that wider chain is a different evidentiary problem.
The extraction-stage question is narrower:
Can the enterprise explain what kind of document fact this field actually is?
FAQs
Is LLM document extraction the same as OCR?
No. OCR identifies text or other page content. LLM-based or generative extraction can interpret that content against a requested schema and may classify, transform or infer values that do not appear verbatim in the document. OCR may therefore supply part of the input without explaining how the final structured field was produced.
Can an inferred LLM field still have source grounding?
Yes, depending on the platform. Microsoft Content Understanding can return grounding for generated document fields, while Google’s current Preview Derived method does not populate the same text and page anchors used for directly extracted fields. The evidence representation therefore has to reflect the platform and extraction method.
What should an enterprise retain with an LLM-extracted field?
At minimum, retain or reference the source document, field/schema definition, provenance method, supporting source grounding where available, extraction instruction or configuration version, model/processor identity and relevant confidence or validation information. The exact retention design depends on the process and regulatory context.
Inference changes the contract of an extracted field
LLMs make document extraction useful in cases that older field-location techniques handled poorly.
They can interpret free-form clauses, normalize variable language, classify semantic conditions and infer structured answers that a downstream workflow can use immediately.
That improvement changes the burden of evidence.
A field copied from a page can often be defended with its location. A field inferred from context needs a richer explanation of what supported it and what instructed the system to produce that interpretation.
Current platforms already expose pieces of this model: direct versus derived methods, explicit versus inferred extraction, generated fields with grounding, prompt-defined schemas, immutable extraction configurations and processor versions.
Enterprises should treat those as parts of the field’s provenance rather than implementation metadata that can be discarded after processing.
Once document extraction can infer the answer, the evidence trail has to preserve more than where the words were found.