
Vision-Language Models for Document Extraction: Layout, Tables and Visual Context in Enterprise IDP
Vision language models for document extraction help preserve the layout, tables, figures and spatial context that give enterprise information its meaning. See where multimodal extraction adds value over deterministic IDP and where conventional document processing still performs better.

Introduction
In enterprise documents, a correctly recognised value can still be wrong for the process if the system loses the structure that establishes what the value represents.
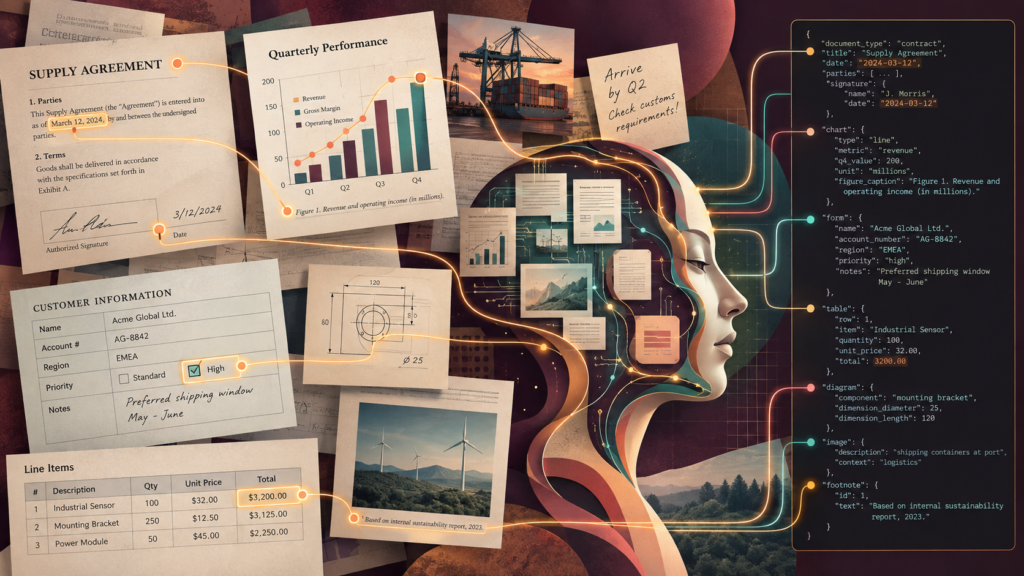
An amount in a financial table depends on its row, column, reporting period and sometimes a footnote. A checkbox in an insurance form takes meaning from the label beside it. A clause in a contract may inherit conditions from a heading several paragraphs earlier. Charts, photographs, handwritten annotations and diagrams can contain information that never becomes ordinary body text.
Document-processing systems have traditionally recovered these relationships through a sequence of technologies. OCR produces machine-readable text. Layout analysis identifies position and reading order. Specialised models recognise tables, key-value pairs and document classes. Extraction logic converts the result into fields required by another application.
Vision-language models alter that arrangement because the rendered document can remain available during interpretation. Text, position, page structure, tables and visual objects can contribute to the same inference.
Google’s Gemini document-processing capability can, for example, analyse PDFs using text together with images, diagrams, charts and tables and produce structured output from that combined input. Microsoft is also separating deterministic document extraction from LLM-based content understanding for documents that require more contextual or multimodal interpretation.
For enterprises, the important development is not simply better OCR. The extraction system can retain more of the evidence that gives a field its business meaning.
That creates opportunities beyond template-based IDP, while placing more responsibility on schema design, validation and the choice of where multimodal inference adds enough value to justify its use.
At a glance
- Vision-language models can interpret document text together with layout, tables, figures and other visual evidence.
- Semantic extraction schemas reduce dependence on fixed field positions where document layouts vary.
- Multimodal processing is most useful where visual or spatial context changes the meaning of the information being extracted.
- VLM-based extraction moves more engineering effort into schema design, grounding, validation and evaluation.
- Deterministic IDP remains economically and operationally attractive for predictable, high-volume document classes.
Layout and spatial structure become model inputs
Modern document automation already extends well beyond character recognition.
Amazon Textract can identify forms, tables, handwriting and layout. Azure Document Intelligence extracts structured and semi-structured information using specialised document models. Similar systems preserve coordinates and relationships because downstream extraction often depends on knowing where text appears.
Vision-language models make that visual representation available directly to the model performing the interpretation.
Take a financial statement containing the value 12.4%. OCR may recognise the number perfectly. The business still needs to know whether it is an operating margin, year-on-year growth rate, benchmark, chart label or value for a previous reporting period.
A conventional pipeline can solve this with table detection, bounding boxes, reading order and extraction rules. A multimodal model can inspect the number together with the surrounding table, headings and page structure.
The difference is more pronounced in documents where position carries meaning. An insurance form may place a checkbox some distance from its label. A clinical report may use one heading for several subsequent rows. Contract obligations can depend on nested sections and indentation. Technical reports routinely combine prose with diagrams and captions.
Microsoft’s Content Understanding tooling reflects this broader representation of the document. It can preserve document elements including sections, tables, figures, signatures and annotations while producing structured output, and its grounding capabilities can associate generated values with relevant source regions.
The resulting extraction process has access not only to recognised text but also to relationships that may be required to interpret that text correctly.
Semantic schemas reduce dependence on fixed document templates
Traditional extraction systems work particularly well where the information required by the business appears in predictable locations or under recognisable labels.
Invoice number, invoice date, supplier name and total amount are good examples. A specialised extraction model can be trained or configured to locate them with high consistency.
Many enterprise questions are less neatly expressed.
A procurement system might need to know the termination provisions in a supplier contract. The information could appear under Termination, Term and Termination, Cancellation, Duration or a renewal section. One agreement may specify a notice period. Another may make termination conditional on an event. Relevant exceptions may appear elsewhere in the document.
The required output could contain the notice period, triggering condition, renewal treatment and applicable exceptions.
Generative document platforms increasingly allow the schema to describe that business information in natural language rather than defining only where a field appears. Amazon Bedrock Data Automation uses extraction blueprints containing fields, types and instructions. Microsoft’s Content Understanding also relies on field definitions and descriptions to guide structured extraction.
The schema can therefore describe both the expected structure of the output and the meaning the system is expected to recover.
That reduces dependence on separate templates for every document variant, but the added interpretive freedom requires stronger evidence handling. A value copied directly from a labelled field is different from a conclusion assembled from several passages. Production systems need to preserve that distinction wherever downstream decisions depend on it.
Tables, charts and mixed-format documents expose the value of multimodal processing
Some of the most important enterprise information is encoded in forms that do not survive cleanly when a document is converted into plain text.
Tables are an obvious example.
Flattening a table can separate a value from the row and column that define it. Multi-level headers create additional ambiguity. Tables spanning several pages can lose their relationship with earlier headings.
Charts create another problem. OCR may identify axis labels, legends and numbers without reconstructing which label belongs to which series or which point represents the relevant value.
Financial reports, engineering documents, research papers, regulatory submissions, insurance claims and lending files routinely combine these structures with ordinary prose.
The business process may need several forms of evidence at once. A credit analyst could require a financial figure together with a footnote that changes how it should be interpreted. A due-diligence workflow may need to compare management commentary with a chart elsewhere in the report. An insurance claim may include photographs that materially affect the assessment.
Keeping those visual relationships available during inference allows the structured result to reflect information that would otherwise have to be reconstructed after the document had already been flattened.
Recent document-understanding benchmarks increasingly include tables, charts, receipts, financial reports and research documents for the same reason. Character or field recognition alone no longer describes the full task.
For enterprise use, the relevant test is whether visual information changes the business interpretation of the extracted result. Where it does, removing that information early in the pipeline weakens the evidence available to the system.
VLM adoption moves engineering effort into schemas, grounding and validation
A model that can generalise across layouts can reduce some template maintenance, but document quality and production requirements remain part of the engineering problem.
Files arrive rotated, blurred, incomplete or poorly scanned. PDFs may mix native text with image-only pages. Tables cross page boundaries. A single file can contain several document types. Handwriting, signatures, stamps and annotations introduce further variation. Google’s document-processing guidance continues to advise correcting orientation and avoiding poor-quality source pages because multimodal processing is still affected by the material supplied to the model.
The output then has to satisfy the requirements of the receiving application. A claims system needs defined fields, expected data types, handling for missing information and predictable behaviour where the evidence is ambiguous. Field descriptions also become operationally important: Microsoft advises providing detailed descriptions, alternative labels, expected formats and useful location information because those instructions affect extraction behaviour.
Evaluation has to cover the same variability. A template-based extractor can often be tested field by field against labelled examples. A system combining visual and semantic evidence also needs test cases for unusual layouts, missing content, ambiguous evidence, mixed document types and interpretations that materially affect the downstream process.
Some effort can move away from maintaining coordinates and layout-specific templates, but it does not disappear. It reappears in schema quality, grounding, evaluation sets, source preparation and exception handling.
High-volume deterministic IDP still has an operating advantage
Multimodal foundation models are not automatically the most efficient extraction engine for every document.
Consider an organisation processing millions of invoices each year from a relatively stable supplier population. The fields are known, document variation is limited, latency matters and extraction accuracy can be measured against established ground truth.
A specialised document model may provide a more predictable operating profile than applying generative inference to every page.
Microsoft’s current guidance reflects this distinction. Document Intelligence is positioned for high-volume deterministic extraction from structured and semi-structured documents, while Content Understanding addresses complex, varied, unstructured and multimodal content.
AWS describes a comparable choice between traditional IDP pipelines and direct multimodal processing. Conventional pipelines remain relevant where processing volume is high, extraction requirements are predictable or organisations want more granular control over individual stages.
A stable invoice with a small set of predictable fields offers limited benefit from expensive contextual reasoning. A 70-page claims file containing forms, narrative reports, handwritten material and photographs presents a different extraction problem. For the invoice, generative inference on every page may introduce cost and variability without adding enough information value. For the claims file, rigid field extraction may omit context needed by the workflow.
Use multimodal reasoning where losing visual, spatial or cross-section context would materially change the business interpretation of the document. Do not use it merely because the source is a PDF or because a VLM is available.
Long documents require more than large context windows
Native support for large PDFs removes an important technical constraint. It does not guarantee uniform extraction quality across the entire document.
Gemini currently supports PDF files up to 50 MB or 1,000 pages, subject to its applicable model and context limits. That makes whole-document submission practical for use cases that previously required extensive preprocessing.
Research still identifies a separate long-document problem. SynthDocBench, published in 2026, evaluated frontier VLMs on controlled long-context visual documents and reported sharp degradation with document length, systematic positional sensitivity and breakdowns in chart comprehension under long-document conditions.
Annual reports, mortgage files, engineering manuals and regulatory submissions may fit within a model’s supported input size while still distributing the relevant evidence across hundreds of pages, tables and appendices.
Segmentation, retrieval and page selection therefore remain useful design choices.
A system processing a 400-page credit file may first identify the sections relevant to covenant analysis before using a multimodal model to interpret the required tables and disclosures. An engineering workflow may retrieve only the diagrams and specifications associated with a particular component.
Whole-document submission is one available technique, not evidence that every extraction task should operate over the complete file.
Hybrid pipelines can reserve multimodal reasoning for difficult evidence
Enterprise document processing is likely to remain a mixed architecture because transcription, structural recovery, repetitive extraction and contextual interpretation have different cost and reliability profiles.
OCR and layout analysis can continue handling text and document structure, while specialised extractors process stable fields at scale. Vision-language models can then be introduced where required information depends on visual relationships, unfamiliar layouts or semantic interpretation that does not map cleanly to a fixed extraction template.
Current cloud-platform architectures already support that combination. AWS describes traditional IDP and multimodal processing patterns, while Microsoft maintains deterministic Document Intelligence alongside LLM-powered Content Understanding rather than treating one as a wholesale replacement for the other.
A procurement workflow could extract invoice headers and line items using a specialised model while routing contract schedules or unusual supporting documents through multimodal analysis. An insurance workflow could process standard claim forms deterministically and invoke a VLM for photographs, handwritten notes or mixed evidence that needs to be interpreted together.
Concentrating multimodal processing on these document classes also makes its cost easier to attribute to information that the business would otherwise lose.
FAQs: vision-language models for document extraction
What are vision-language models for document extraction?
Vision-language models analyse visual document content together with language.
In document extraction, they can use text, layout, tables, figures, spatial relationships and other visual information while producing structured data for downstream systems.
Do vision-language models replace OCR?
No.
OCR remains an effective technology for text recognition and continues to be used inside many modern document-processing architectures. Some systems combine specialised OCR with multimodal models, while other workflows send rendered document pages directly to a vision-language model.
The appropriate design depends on document complexity, processing volume, latency, cost and the amount of meaning carried by visual structure.
Which documents benefit most from multimodal extraction?
The strongest candidates contain information whose meaning depends on variable layout, tables, charts, figures, handwritten content, annotations or relationships between several parts of the document.
Predictable forms with stable fields may still be processed more efficiently through deterministic IDP.
Can vision-language models return structured data?
Yes.
Enterprise document platforms can define schemas containing strings, dates, numbers, arrays and nested structures. The model interprets the document against that schema and returns information in a form suitable for application processing.
What should enterprises test before using VLMs for document extraction?
Evaluation should include document variants, poor-quality inputs, complex tables and figures, ambiguous or missing information, long documents and cases where incorrect extraction would materially affect the downstream process.
Testing should also confirm that important outputs can be traced back to enough source evidence for review.
Multimodal extraction should follow the information requirement
The evidence required to establish the business fact should determine whether a workflow needs deterministic or multimodal document processing.
Some processes primarily need accurate transcription. Others need a known set of fields from predictable documents. More complex cases depend on relationships among text, layout, tables, images and information distributed across several parts of the document.
Vision-language models make those cases more accessible because the visual and spatial evidence does not have to be discarded before interpretation.
For enterprise architects, the decision is therefore about identifying where the existing document pipeline loses information that the receiving business process still requires. Where that loss changes the interpretation of the document, multimodal processing has a clear role.